Operators do not distrust automation because they fear technology. They distrust it because they have been blamed when a silent job fired twice, skipped a row, or emailed the wrong client. Trust is a product requirement. If they cannot see what ran, they will keep a shadow process in a notebook.
Show the queue, not just the success toast
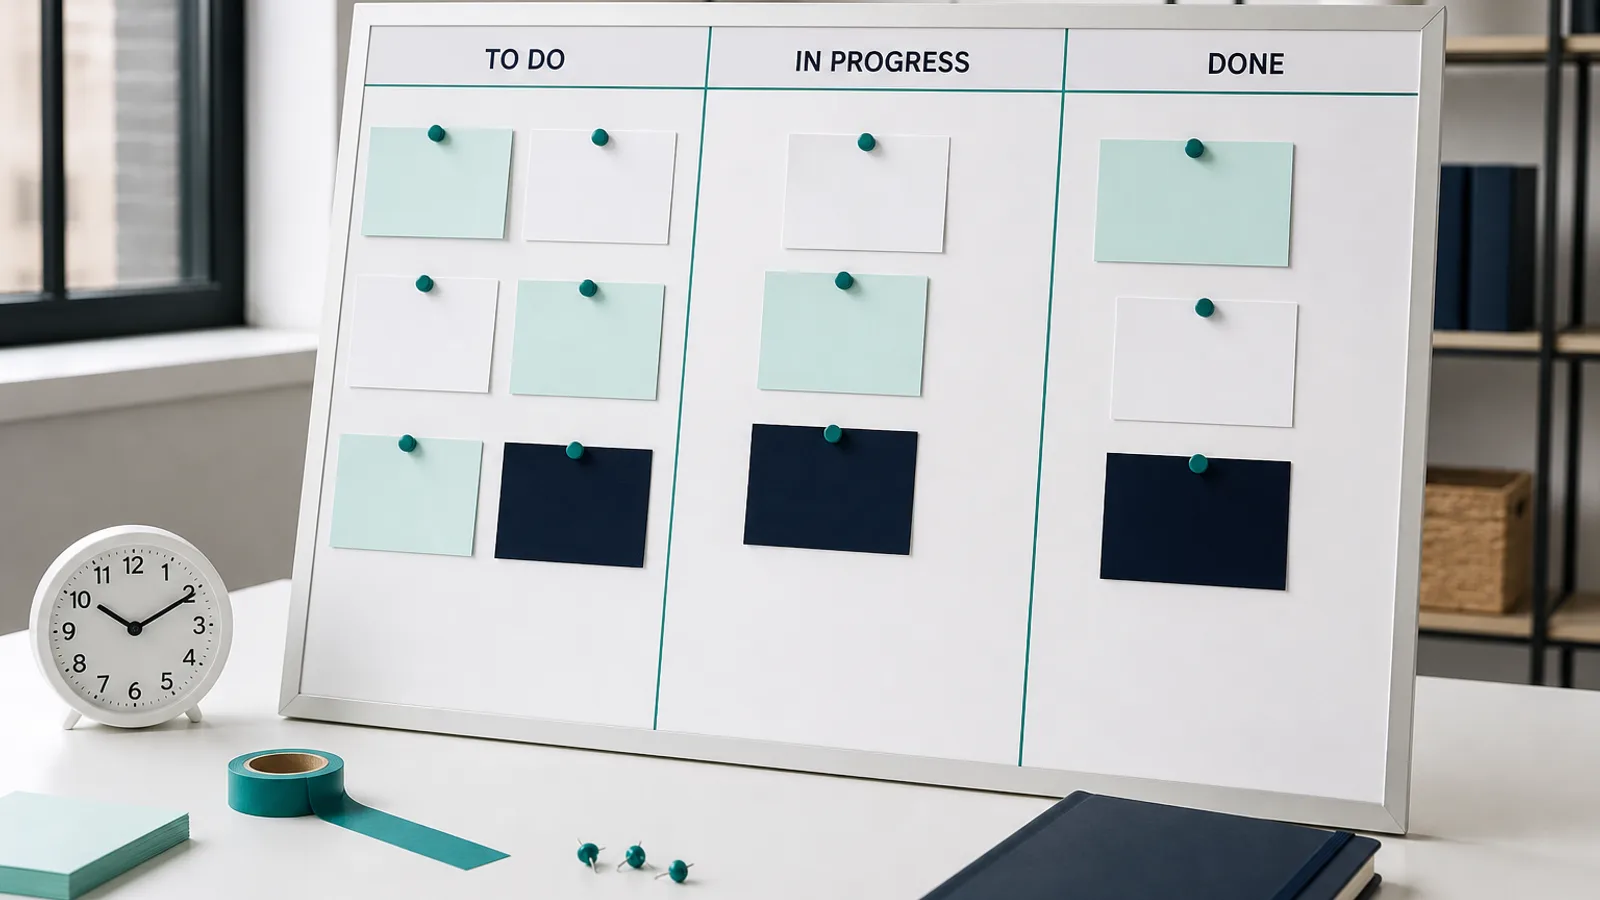
A good automation has a list: waiting, running, done, failed. Each item names the record and the last step. Failed items stay failed until a person says otherwise. Hidden retries that “fix themselves” are how duplicates enter the CRM. Make the queue a screen. If it is only in a log file, it does not exist.
- Idempotency keys. The same event must not create two invoices.
- A stop button. Someone on the floor has to be able to halt a run.
- A replay that is explicit. Replay is a choice, not a side effect of refresh.
Automate the boring path first
Start with the case that happens forty times a week, not the exception that happens twice a year. Exceptions stay manual until the happy path is boring. Then encode the next exception only if it has a name and a rule. A workflow that tries to handle every edge on day one will fail in a way nobody can explain.
Hand it to the people who run Monday
If only engineering can restart a job, the automation is still a project. Give operations a screen, a owner, and a rule for when to call engineering. That is how Stacknify ships automation: into the week, not onto a slide. When Monday is quieter, you built the right thing. When Monday still needs a hero, you built a demo.